Skip to content
quineFXResumeContact

04 · R&D on my own machine

Lab

Nothing on this page was commissioned. It is where I try new open-weight models on my own workstation, find where they break, and build the pipelines I trust. Some of it ends up in client work: the voice de-aging behind Making Freedom Fly started here.

6 write-upsR&D, not commissions

  1. 01

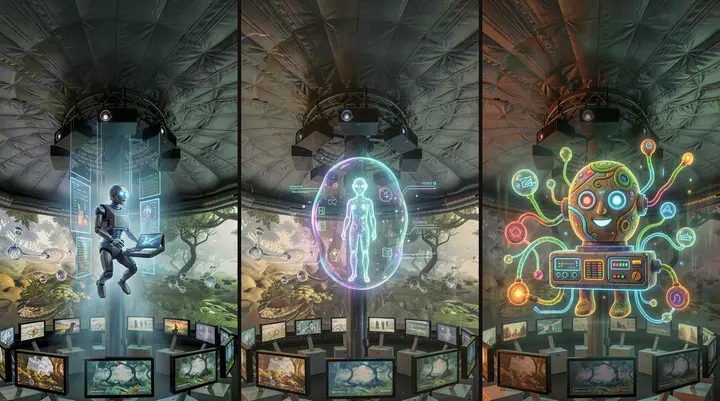
    The Column Auditions

    Casting an AI helper for the centre column of Within Our Reach, an interactive dome: one room held still, one sentence of prompt, twelve candidates, all generated on my own machine.

    Year
    2026
    Role
    Character concept and pipeline
  2. 02

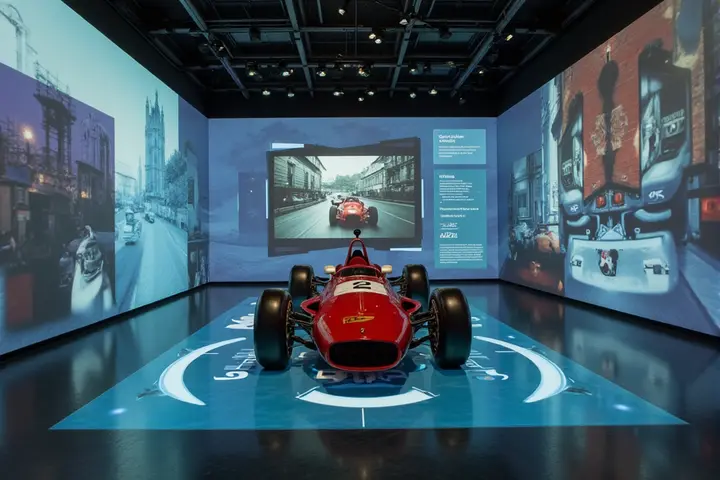
    Pixelated Portals

    Concept renders for immersive rooms, made with LoRAs trained on decades of my own installation mockups.

    Role
    Creative Technologist
  3. 03

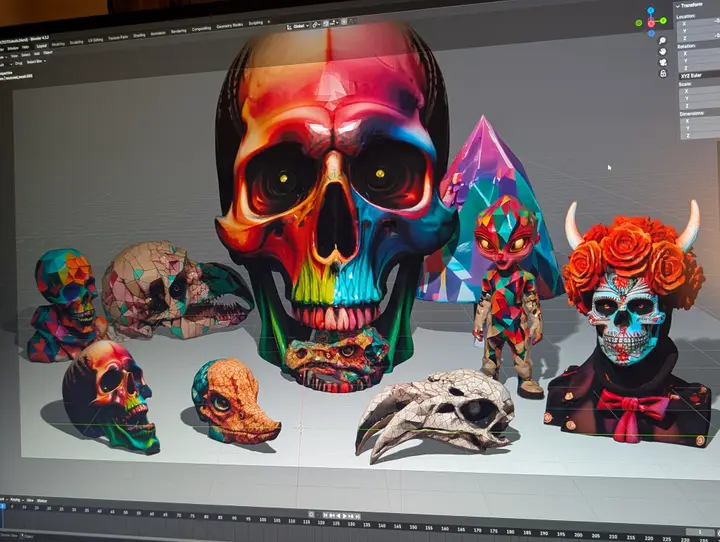
    Open-Source 3D PBR

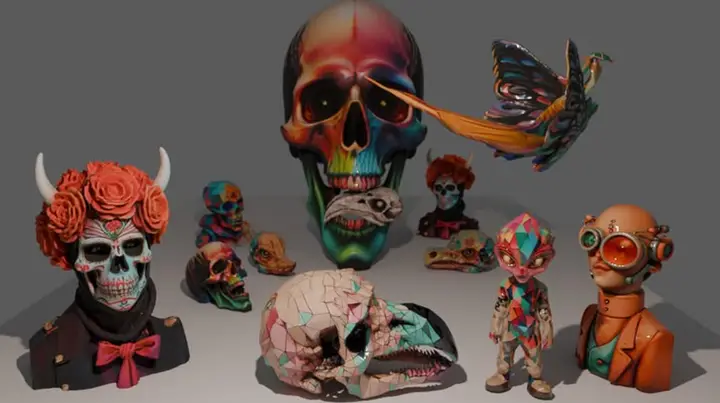
    Testing open-source image-to-3D models (TRELLIS, SAM 3D, Hunyuan3D) on a single RTX 4090, then taking the results into Blender and Unreal.

    Role
    Creative Technologist
  4. 04

    Action Figures

    Toys that never existed: 1970s-style action figures in boxes and blister packs, iterated with image-to-image workflows in ComfyUI.

    Role
    Creative Technologist
  5. 05

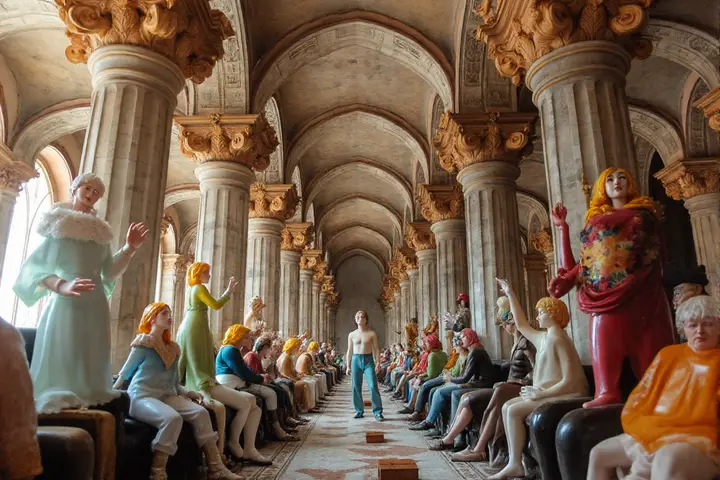
    Other Worlds

    An R&D series of impossible halls: one-point-perspective corridors lined with figures, iterated with custom LoRAs in ComfyUI.

    Role
    Creative Technologist
  6. 06

    AI Crucible

    A running log of experiments at the edge of local AI video and sound. Mostly failures. Updated often.

    Role
    Creative Technologist

01 · Fragments

In progress

Works in progress, pipeline experiments, things that broke interestingly.

  • flux2 comfy flow testPipeline experiment flux2 comfy flow test
  • LoRA trained on my partner's felted sculpturesComfyUI workflow LoRA trained on my partner's felted sculptures
  • blender rendersCharacter WIP blender renders
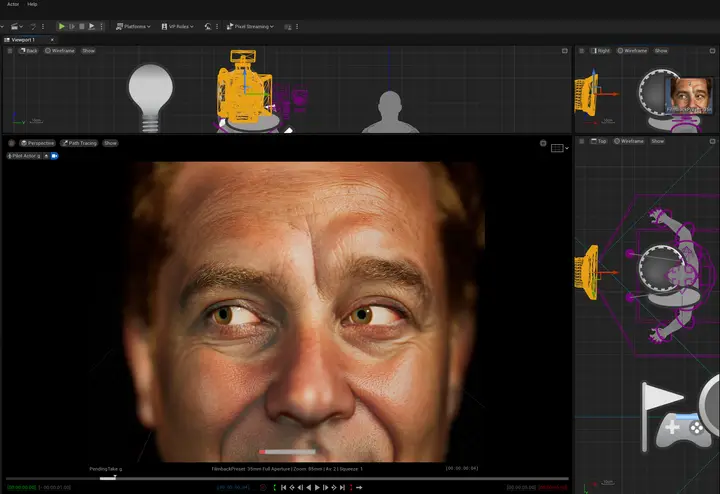
  • metahuman skinUnreal lighting test metahuman skin
  • early explorations in LoRA creationCustom LoRA early explorations in LoRA creation
  • interactive install mockupEnvironment test interactive install mockup
  • glass refractionRender study glass refraction
  • trained on my dad's paintings and my speaker cabinet designsCustom LoRA trained on my dad's paintings and my speaker cabinet designs
  • site concept with threejsCustom LoRA site concept with threejs

02 · How an image arrives

From noise, step by step

Every generated image on this site starts as random noise and is resolved, step by step, by a model running on my own machine. This one finishes as you scroll. The settings underneath are the real ones, read from the file.

“portrait of felt molecules mounted to cabin wall. dynamic lighting. glowing”

730GB

of models on local drives

184

LoRAs in the library

129

saved workflows

24GB

of VRAM on the workstation GPU

03 · The library

730 GB of models,
all of them local

Every block is a model folder on the workstation, sized by weight on disk. Hover for detail.

  1. Diffusion models190.1 GB
  2. Local LLMs107.5 GB
  3. Text encoders85.0 GB
  4. CLIP63.5 GB
  5. Video: LTX-2.5, MiniMax H359.0 GB
  6. Checkpoints49.7 GB
  7. LoRAs48.7 GB
  8. SeedVR2 video upscaling33.2 GB
  9. Image: Krea 2, Qwen Image 2.119.0 GB
  10. SAM 3 segmentation15.1 GB
  11. + 13 smaller folders
Image and videoLanguage3D, characters, real timeSound 

04 · The elements

A periodic table
of the stack

A traditional design stack on the left, a contemporary AI stack beside it. Everything here is installed, wired together and used on real work. Select an element.

Design stack
Image
Video
Voice
Language
3D
Real time

05 · Systems

Pipelines that talk,
sing and listen

Marchivum, Mannheim · 2025

A historical figure you can talk to

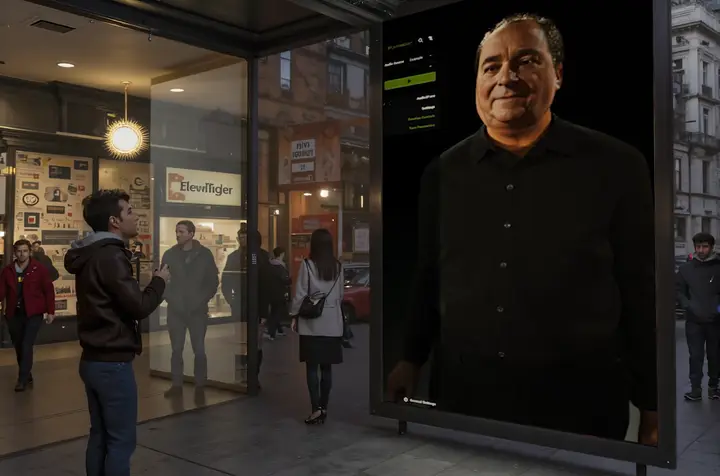
Visitors ask Carlo Schmid a question out loud. He answers in his own cloned voice, from the archive's documents, with a face animated by the audio. Every model runs locally, on one machine.

~1.2 s
average response
256 / 64
token chunks / overlap
0
cloud calls
  1. 01Visitor speaksmicrophone
  2. 02Whisperspeech to text
  3. 03Hybrid retrievalFAISS 70% + BM25 30% over OCR'd archive documents
  4. 04Mistrallocal LLM, in character
  5. 05XTTS v2cloned voice, streamed sentence by sentence
  6. 06Audio2Facelip-sync and expression from the audio
  7. 07MetaHumanrendered live in Unreal Engine 5
Making Freedom Fly · 2023–24

Giving veterans back their younger voices

Each voice is split into separate envelopes, re-aged one at a time, then trained on a blend of the original and the re-aged audio so it still sounds like the same person.

60 min
of source audio each
< 2 s
to generate a line
10–100×
less data than standard training
  1. 0160 minutesof each veteran, recorded now
  2. 02Envelope splitpitch · timbre · formants · phonetics
  3. 03Per-envelope modulationweights tuned until the artifacts go
  4. 04Blended trainingoriginal + re-aged audio
  5. 05Real-time voiceunder two seconds per line
Avatar chat · 2026

A voice avatar that lives in the browser

Speak, and an abstract avatar listens, thinks and answers out loud, its surface driven by the frequencies of its own voice. The whole loop fits in a third of the GPU.

1.4–2.5 s
speech to first reply
8.5 GB
of 24 GB VRAM
3
local servers
Whisper 3 GBLlama 3.1 8B 5 GBKokoro 0.5 GBfree 15.5 GB of 24
  1. 01MicrophoneAudioWorklet, 16 kHz
  2. 02faster-whisperlarge-v3-turbo on CUDA
  3. 03Llama 3.1 8Bvia Ollama, streaming
  4. 04Kokoro82M-parameter TTS
  5. 05FFTbass · mid · high bands
  6. 06Three.js avatarshader orb + 3,000 particles

06 · Every image carries its recipe

A quine produces
itself as output

ComfyUI writes the full workflow into every image it saves. These graphs were read straight out of the portfolio images on this site. LoRA and source names are withheld.

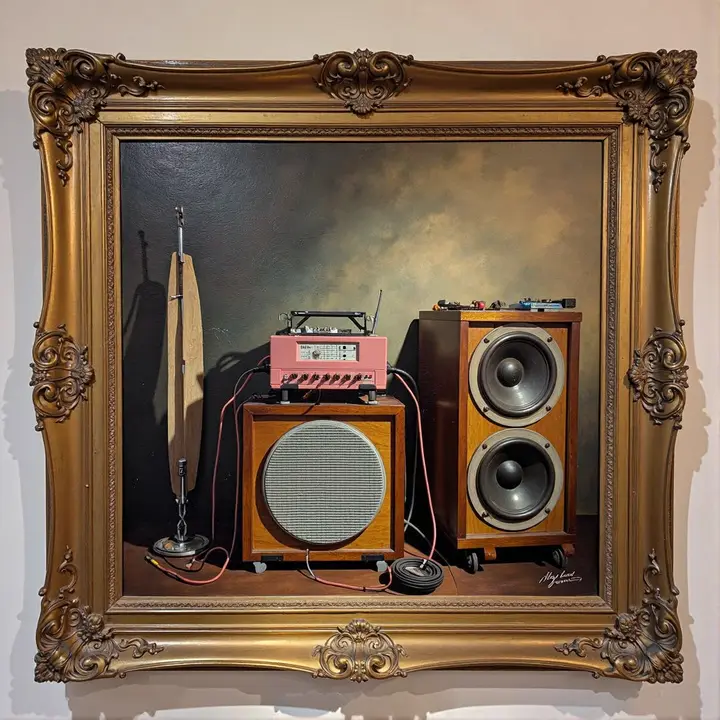
Painted amplifiers

Painted amplifiers

Two in-house LoRAs, one trained on my dad's paintings, steering a ControlNet pass.

Model
flux1-dev
Steps
20 · dpmpp_2m
Nodes
14
LoRAs

+ framed oil painting of vintage amplifiers, speakers and cables

− boring

Diffusion modelflux1-devVAEaeSampler20 steps · dpmpp_2m Empty latentEmptyLatentImageDecodeVAEDecodeSaveSaveImageText encoderst5xxl_fp8_e4m3fn + cPromptCLIPTextEncodePromptCLIPTextEncodeSource imageLoadImageScaleImageScaleLoRAstrength 0.80LoRAstrength 1.10

07 · Output

Made on the machine

Carlo SchmidMetaHuman + Audio2Face
SkullsImage to 3D, lit in Blender
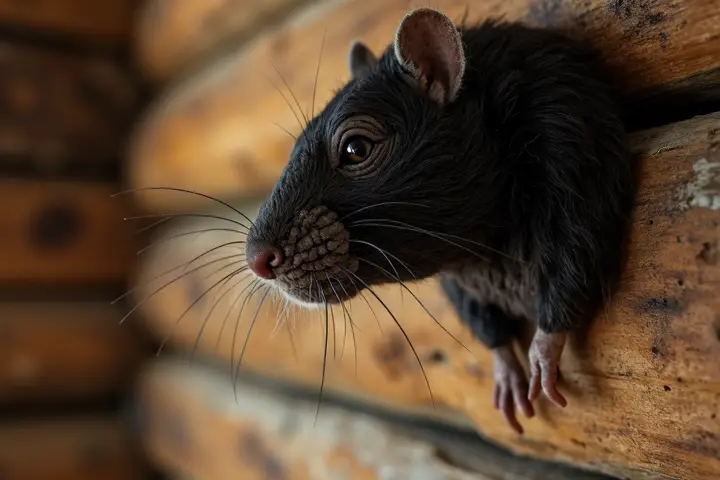
Don't feed the animalsImage to video
Immersive roomA LoRA of my face, projected into a space
GTOFrame-by-frame generation
Boy in a boxLTX Video
BananasImage to video
Self, drawnStyle transfer on my likeness
Self, paintedStyle transfer on my likeness
PixelCharacter animation
Behind CarloAudio2Face into Unreal, live

08 · Why local

Nothing leaves
the room

01

Your material stays in the building

A museum's collection, a studio's unreleased frames and character designs: none of it has to leave your own network to be worked on.

02

Installations outlive APIs

An exhibit has to run for years. No service shutdowns, rate limits or price changes.

03

Voices and faces stay private

Clones of real people are trained and run on hardware I control, and never uploaded.

04

Everything is tunable

Custom LoRAs, node packs and compiled engines, not whatever a vendor ships this month.